Posts

Showing posts with the label NGS

Screen for mycoplasma contamination in DNA-seq and RNA-seq data: Part 2

Image
If you're culturing cells, avoiding contamination is an extremely important priority. Mycoplasma are common contaminant that can change the behaviour of cells and don't cause any obvious morphological changes, so routine testing is key. As bioinformaticians we should be incorporating myco screening into all our workflows, but the available tools haven't been that great. Even the shell script I wrote in a previous blog post isn't that great. It suffers from a few problems in miscounting reads, usability and leaving many files in the working directory. So it is high time for a refresh. With this refresh, the idea was to make a command line tool that folks could easily incorporate into their workflows, would process single- and paired-end data, be quick and be concise in its output. The result is `contam`. To give you an idea of what it can do, here is the help page: contam is a script for the quantification of contaminant sequences in Illumina short read sequence data i...

Screen for mycoplasma contamination in DNA-seq and RNA-seq data

Image
**An update to this post has been published here  (Oct 2024)** M. haemofelis infection in blood smear. Courtesy of Wikipedia . If you work in a lab dealing with mammalian cell cultures, then you've probabaly heard of Mycoplasma , these are obligate intracellular parasitic bacteria that not only cause human infection and disease, but also common contaminants in cell culture experiments. Mycoplasma infection can cause many changes to cell biology that can invalidate experimental results which is alarming. These bacteria are also resistant to most antibiotics used in culture experiments like streptomycin and penicillin. Mycoplasma detection is also not straight-forward, as these bugs are not visible with the light microscopes used by most researchers. PCR and Elisa tests can be used but there many researchers out there who simply don't perform these tests. Last year, a study published in NAR showed that about 11% of RNA-seq studies were affected by Mycoplasma contamination, f...

Mapping NGS data: which genome version to use?

Image
Aligning reads to the genome is a key step in nearly all NGS data pipelines, the quality of an alignment will dictate the quality of the final results. So for beginners in this space, the options available can be a bit overwhelming. Which options are available? Depending on what species you are working on, you will have either a limited number of choices or a vast number of choices. These include NCBI, Ensembl, UCSC as well as the consortia that generate these genome builds, such as the Human Genome Reference Consortium for human and TAIR for Arabidopsis. My recommendation at this point is Ensembl, for a number of reasons: It is clear to see what genome build and version just from the file names. Contrast "hg38.fa.gz" for UCSC vs "Homo_sapiens.GRCh38.dna_sm.primary_assembly.fa.gz" for Ensembl From the Ensembl file name you can tell whether its masked, and whether its "primary assembly" or "toplevel". The website is intuitive, ftp do...

Quantifying repeat sequences from short read next gen sequencing data

Image
Repetitive sequences pose significant challenges for the analysis of short read sequence data. Any sequence read that is shorter than the repeat unit is going to fail at being uniquely placed in the genome. At a given read length, genome can therefore be divided into mappable and unmappable compartments. For analyses such as gene expression and chromatin profiling, we generally ignore those unmappable regions and ignore reads that map to multiple positions. But what if we were actually interested in the abundance of repeat sequences in the dataset? How could it be quantified with short read sequencing? Why is that even relevant? The "Why" About 50% of the human genome is comprised of repetitive DNA ( Ref ). While the function of these elements in many cases remains unknown, some have been well defined. Alu elements have been shown to be a birthplace of enhancers ( Ref ). Endogenous retroviruses have been domesticated to boost antiviral response in B cells after exposure t...

microRNA aligners compared

Image
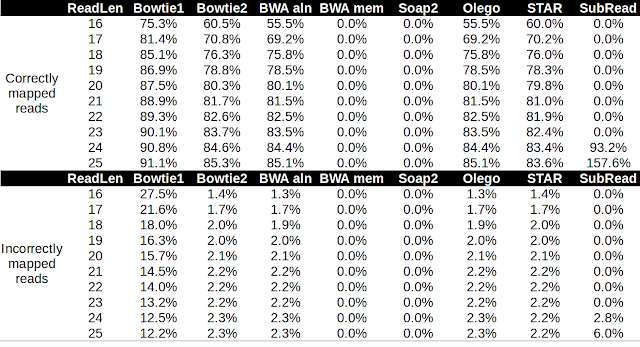
Alignment of microRNA to the genome poses a particular challenge because the reads are short, and some microRNAs are nearly identical. Moreover, microRNAs themselves are subject to RNA editing ( adenine-to-inosine conversion , non-templated base addition ) and normal sequencing error rates. In this post, I'm going to test the performance of several aligners in aligning microRNA reads to the Arabidopsis genome.  I downloaded the Arabidopsis genome from  Ensembl plant  and the latest  miRbase release version 21 . I used bowtie2 to align the 325 full-length hairpin transcripts to the Arabidopsis genome. I generated pseudo microRNA reads that uniformly cover the hairpin transcript at a range of lengths from 16 nt to 25 nt. I then aligned the reads to the Arabidopsis genome using these different aligners with the default settings. I then used bedtools and awk to count the correctly and incorrectly mapped reads at a mapQ threshold of 10.  Table 1. Performan...

Data analysis step 2: quality control of RNA-seq data

Image
In a previous post , we downloaded RNA-seq data from GEO ( GSE55123 ) . Lets continue with the processing of this data by performing QC analysis. In a previous post , I went into a bit more detail, but here we will simply use fastx_quality_stats from the fastx toolkit to have a look at quality scores among the data sets. The general strategy was to unzip the data on the fly, convert to tabular format and then select a random 1 million sequences and then submit these to fastx_quality_stats. So having a look through the output file, shows very high quality scores with median scores >36 which suggests this dataset is very high quality. Below see the code used and a graph of median quality scores throughout the run. #!/bin/bash for FQZ in *bz2 do echo $FQZ pbzip2 -dc $FQZ | paste - - - - | shuf | head -1000000 \ | tr '\t' '\n' | fastx_quality_stats | cut -f1,6-9 done | tee quality_analysis.txt Mean cycle base quality for GSE55123 RNA-seq data shows very h...

Quick alignment of microRNA-Seq data to a reference

In my previous post , I discussed an efficient approach to align deep sequencing reads to a genome, which could be used for most applications (mRNA-Seq, ChIP-Seq, exome-Seq, etc). MicroRNA datasets are rather a bit different because they often contain millions of reads from only a few thousand RNA species, meaning there is a lot of redundancy. We can speed up this analysis considerably if we collapse the sequences and remove the redundancy before genome alignment. You can see in the below script that several steps are done without writing a single intermediate file: Adapter clipping Sequence collapsing BWA alignment Bam conversion Sorting bam file for FQ in *fq do fastx_clipper -a TGGAATTCTCGGGTGCCAAGG -l 18 -i $FQ \ | fastx_collapser \ | bwa aln -t 30 $REF - \ | bwa samse $REF - ${FQ} \ | samtools view -uSh - \ | samtools sort - ${FQ}.sort & done wait for bam in *bam ; do samtools index $bam & done ; wait for bam in *bam ; do samtools flagstat $bam > ${bam}.sta...

Align Next Gen Sequencing Data Like A Boss

We know that sequencing platforms are generating more and more output, and more of this data is finding itself in online databanks. The volume of data is a blessing because it is so information rich, but it is also increasingly becoming a problem - we need more machine time to process it. I was recently aligning dozens of mouse encode RNA-seq data sets while we had a server fault. I was left with a mess of half finished jobs and intermediate files and basically had to start the whole process again. This prompted me to make an alignment pipeline that would be more resistant to unexpected interruptions. To do this, I took inspiration from a post at SEQanswers which piped the output from the BWA aligner and generated bam files without any intermediate files. But I wanted to take this a bit further, by going from compressed fastq to bam file without writing any intermediate files, doing quality trimming on the fly and saving a lot of storage in the process. So here are two examples, o...

Generate an RNA-seq count matrix: Part 2 - count over exons

Image
In the previous post , I mentioned that in order to do counting, we need some regions (exons) to count over. We generated a BED file based on GENCODE exons which looks like this: chr9 33248310 33248419 ENSG00000107262.11_BAG1 chr9 33252477 33255306 ENSG00000107262.11_BAG1 chr9 33255862 33255925 ENSG00000107262.11_BAG1 Now we can actually count how many reads from each of our samples maps to these exons. To do that there are a few different programs: htseq-count samtools view GATK countreads Bams2mx BedTools  multicov For this demo, I will outline use of BedTools for RNA-Seq. I think BedTools nulticov is a good option for 3 main reasons: It can handle multiple bam files at the same time, producing a count table/matrix which is pretty much ready for statistical analysis. It is aware of mapQ scores of alignments, meaning that if the program comes across non-unique alignments, you can set it to ignore or include those reads. The BedTools package is well ...

Library preparation for RNA-seq

It is often said that RNA-seq is overtaking microarray as the gold-standard for transcriptome wide gene expression analysis, but what most people don't understand is, that this "gold standard" is far from standard. There are an ever increasing number of methods available to apply high throughput sequencing to gene expression analysis. Thus "RNA-Seq" is actually very generic term describing a range of techniques which aim to use sequencing to profile transcripts. Let's go through some of the more common applications  and work our way to the more niche applications. mRNA-Seq This method aims to profile the pool of transcripts which encode for proteins. The idea is to enrich the RNA mixture for mRNAs by depleting the concentration of rRNAs and other abundant ncRNAs. Usually, this is achieved by polyA enrichment using hybridization to magnetic beads decorated with oligo dT strands. After the enrichment the resulting RNA is fragmented by heat exposure in the ...

Bowtie alignment to a genome - single end

Recently I posted about  BWA alignment of NGS data, so today I will demonstrate the use of Bowtie2  for aligning single end sequence data, for more information on advanced options, take a thorough look at the manpage . One of major strengths of Bowtie2, is that it's more tolerant for gaps than Bowtie1 and  BWA. Again you will need to have the reference genome and the raw fastq files in the otherwise empty directory. The first thing we do is stipulate the name of the experiment and the name of the reference sequence. EXID=Experimentname REF=Hg19.fa Now index the genome with bowtie2-build: bowtie2-build Hg19.fa Hg19.fa Now to actually start the alignment for all the files with prefix "FC" and suffix "fq": for FQ in `ls FC*fq | sed 's/.fq//'` do bowtie2 -x $REF -U ${FQ}.fq -S ${FQ}.sam -p 4 --met-file ${FQ}.met 2> ${FQ}.stats & done wait The script starts aligning all fq files to the human genome in parallel and each job uses 4 thre...

BWA alignment to a genome - single ends

Over the last few posts, we've discussed various ways to analyse the quality of a sequencing run, and curate the data sets in terms of demultiplexing , quality trimming and adapter clipping . I guess the next step is alignment. There are an increasing number of aligners out there for short read sequencing (listed here ), but currently the most popular choices are BWA and Bowtie2 . BWA is a quick and accurate tool, but might not be the best for gapped alignments (common in mRNA-Seq). Today I will demonstrate how to align short reads (single end) with BWA and convert the alignment to bam format with  Samtools . The things you will need in the otherwise empty directory are: Reference genome in fasta format Sequence data in fastq format (.fq) First thing to do is give the experiment a name and index the genome with BWA. The index step could take about 3 hours for a human size genome. EXID=Experimentname REF=Hg19.fa bwa index -a bwtsw $REF Next, use BWA to ali...

Paper of the week - Next gen sequencing of ancient DNA

Image
This paper was featured in the 12 October issue of Science, so really isn't from this week, nevertheless I thought it would be relevant given the previous post on library preparation. Sequencing ancient DNA is a hugely challenging task. Not only is it very difficult to get any sort of yield of DNA from bones tens of thousands of years old, but the DNA itself is normally degraded to such an extent that conventional library preparation is highly inefficient. On top of this, there is the challenge to eliminate environmental contamination. To avoid much of this, the team, lead by Matthias Meyer at the Max Planck Institute for in Leipzig came up with a simple but efficient method to generate sequencing libraries from single stranded DNA. The basic steps in the library prep are: Dephosphorylate Heat denature Ligate single stranded biotinylated adaptors Immobilize on streptavidin beads Generate the second strand with DNA polymerase Ligate a second adaptor by blunt end ligation ...