Posts

Showing posts with the label pathway analysis

Now published: Ten common mistakes that could ruin your enrichment analysis

Image
  Glad to share with you our published article  Ten common mistakes that could ruin your enrichment analysis . The work was done by Anusuiya Bora (Burnet Bioinformatics, Deakin Uni), Matthew McKenzie (Deakin) and I. My working group got interested into pathway enrichment analysis in around 2020/2021 because I was receiving review requests for manuscripts and many of them suffered from severe problems, leading me to believe that these issues were prevalent. Our first article on this theme  Wijesooriya et al, 2022  demonstrated that severe problems were really common across a big sample of peer-reviewed articles including: Lack of p-value correction. Wrong background list. Lack of methodological details. We showed that problems 1 and 2 led to dramatic biases in results that could alter the conclusions of transcriptome studies. Due to reviewer disagreements, we were unable to provide a more comprehensive set of best practices in that article, but this remained a priorit...

Workshop alert! Mastering Reproducible Enrichment Analysis

Image
 Join us for a 2-part workshop on Mastering Reproducible Enrichment Analysis! 📊 Presented by Anusuiya Bora and myself, with a focus on reproducibility and best practices. 📅 When: 12 and 13 May 2026  🕑 Time: 2:00 PM – 4:00 PM (AEST)  📍 Where: Online  💰 Cost: FREE for academic sector (places are limited!) 🔗Registration form link: https://tinyurl.com/ye262hzx

Mitch gets upgraded - now with gene set networks

Image
Interpreting pathway enrichment analysis results is a big challenge. There may be hundreds of statistically significant pathways from an analysis and getting to a shortlist of key mechanisms to follow up with experiments and describe in a publication is difficult. I recently got a request from a collaborator to come up with a way to visualise the key networks. I groaned... because network analysis in bioinformatics is sometimes characterised by showing hairballs of hundreds/thousands of meaningless interactions. Mostly it is done poorly and the charts themselves do not have any explanatory function and mostly appear to be decorative. After seeing a few well done examples such as Figure 2 from Chappel et al (PMID: 32138627), I thought this could be something we include as a common step in the mitch workflow. For those of you unaware, mitch is the R/bioconductor package that Dr Antony Kaspi and I published in 2020 (PMID: 32600408) with the main focus being on multi-dimensional enrichmen...

Yes, mitch can be used for pathway analysis of Methylation array data

Image
In 2020, Dr Antony Kaspi and I published a method called "mitch" [1] which is like GSEA, but was specifically designed for multi-contrast analysis, and based on rank-MANOVA statistics inspired by a 2012 paper by Cox and Mann. Mitch worked well for various types of omics data downstream of commonly used differential abundance tools like DESeq2, edgeR, DiffBind, etc, but we didn't consider at the time how mitch could be applied to microarray data.  You might think that microarrays are outdated, but they are still used extensively for epigenome-wide association studies (EWASs), which are frequently used to understand disease processes and to identify biomarkers of disease. To demonstrate, there are 1536 publicly available methylation array studies on NCBI GEO, and probably many more thousands that are restricted access. The tools available for pathway analysis of methylation array data are a bit limited. There's an over-representation method that take into consideration ...

Don't use KEGG!!!

Image
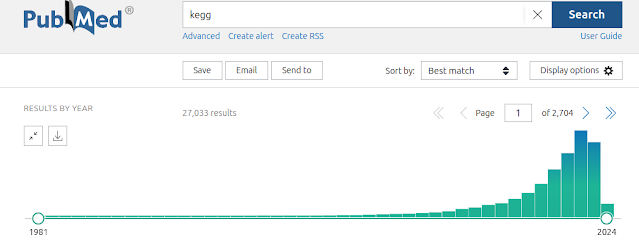
KEGG is the Kyoto Encyclopedia of Genes and Genomes, a compendium of gene functional annotations which are commonly used for pathway enrichment analysis. KEGG has been around since 1997 (PMID: 9390290) but in 2000, as the draft human genome sequence was released, KEGG became a key database involved in the curation of literature data to catalog the function of all human genes, many of which were newly sequenced and previously uncharacterised. This invigorated interest in KEGG is demonstrated by one of their articles in 2000 (PMID: 10592173) accruing 24,236 citations according to Dimensions , 1270 fold higher than other articles from that time. A PubMed search using "KEGG" keyword shows 27,033 results, with matches in abstracts alone and the tragectory is increasing at a rapid rate. Despite the popularity of this tool, I'm urging you not to use it for your research. Here I will lay out the reasons. 1. It isn't comprehensive I did an analysis of KEGG and other pathway se...

Understanding pathway-level regulation of chromatin marks with the "mitch" Bioconductor package (Epigenetics 2021 Conference Presentation)

Image
Presented 18th February 2021 Abstract Gene expression is governed by numerous chromatin modifications. Understanding these dynamics is critical to understanding human health and disease, but there are few software options for researchers looking to integrate multi-omics data at the level of pathways. To address this, we developed mitch, an R package for multi-contrast gene set enrichment analysis. It uses a rank-MANOVA statistical approach to identify sets of genes that exhibit joint enrichment across multiple contrasts. In this talk I will demonstrate using mitch and showcase its advanced visualisation features to explore the regulation of signaling and biochemical pathways at the chromatin level.

Mitch: An R package for Multi-Contrast Gene Set Enrichment Analysis

Image
Gene set enrichment is one of the key methods in the understanding of gene expression patterns. As omics are becoming more widely used, large experiments are common and include not just one contrast (control vs case), but perhaps many contrasts (eg: healthy, disease, treatment 1, treatment 2, etc). Previously, as part of an epigenetics/epigenomics lab we were looking at ways to integrate different types of omics profiling such as RNA expression, histone acetylation and DNA methylation. We stumbled across a paper that proposed the use of multivariate ANOVA on ranks ( Cox & Mann 2012 ) to identify gene sets that exhibited enrichment in one or more contrasts. We thought this could be a simple way to identify gene set enrichments when looking at multiple contrasts without the need to run GSEA multiple times and summarise the results. The tool described in Cox & Mann (2012) is written for the Perseus suite which works for Windows. We saw there was no similar implementation in R so...