Posts

Showing posts with the label gene expression

Incorporate dee2 data into your R-based RNA-seq workflow

Dee2.io is a portal for accessing gene expression data derived from public RNA-seq datasets. So far there are over 400k available datasets and its growing every day. While there are existing databases of such as Expression Atlas , Recount2  and ARCHS4 , dee2.io offers a number of unique benefits. For instance, dee2 includes gene-wise counts fron STAR as well as transcript-wise quantifications from Kallisto. There are a few ways you can access these data. Firstly, there is a nice web interface that is mobile friendly. Secondly, there are data dumps available if you are running a large scale analysis.  But the purpose of this post is to demonstrate the improved R interface in action together with SRAdbv2 and statistics with edgeR and DESeq. The official documentation is available on  GitHub . Getting started This tutorial provides a walkthrough for how to work with dee2 expression data, starting with dataset searches, obtaining the data from dee2.io and then performing...

Has RNA-seq overtaken microarrays?

Image
We know RNA-seq has a number of advantages over array based analyses, but is RNA-seq taking over in terms of number of datasets published? I got curious and thought I'd investigate with some PubMed searches. I searched for "RNA-seq" and "microarray" and downloaded the CSV file which summarises the number of citations per year. As a type of control, I also searched "gene expression". I divided the yearly "RNA-seq" and "Microarray" citation counts by the "Gene expression" counts then multiplied by 1000 to give the numbers seen below. You can see that microarray is still more frequent in PubMed as compared to RNA-seq, but the gap is getting much narrower and the cross will likely occur in the next two years. Next, I will look at the rate of GEO data deposition. (Updates soon)

Analyzing repeat rich plant smRNA-seq data with ShortStack

Image
Small RNA expression is difficult to analyse. They're small molecules anywhere from 18 -25 nt for miRNAs, they occur as identical or near identical family members and are subject to RNA editing as well as errors from the sequencer. My recent paper  is an analysis of alignment tools for microRNA analysis with a strong focus on uniquely mapped reads. All that's OK, but in some organisms such as grasses (rice, barley, wheat, etc) you'll find that multimapped reads far outnumber uniquely placed ones. If you omit multimapped reads from the analysis, then you'll be excluding the majority of reads which is definitely a bad idea in any NGS analysis pipeline. To demonstrate this, I downloaded smRNA-seq data from SRA ( SRP029886 ) that consists of 3 datasets (SRR976171, SRR976172, SRR976173), clipped the adaptors off and mapped them to the genome with BWA aln then counted reads mapped to exonic regions uniquely (mapQ ≥ 10). Table 1. Mapping of rice small RNA reads to the ...

How to generate a rank file from gene expression data in R

Previously I wrote about how to make a gene expression rankfile using the unix shell. While this works for me just fine, there are some differences in the behaviour of shell tools like awk an sed that make it unusable for mac users. Therefore, I think the best solution is to show you how to do this in R, which you can install on Linux, Mac and Windows systems. The expression data for this demo looks like this (the first 5 columns). Name                        logFC               logCPM            LR                PValue ENSG00000134294.9_SLC38A2   0.365464972841137   8.35504063447063  80.9697378748286  2.29200821312451e-19 ENSG00000164692.13_COL1A2   0.369440969815233   6.9371167845581   59.239238358843   1.39621819298599e-14 ENSG00000117152.9_RGS4      ...

Is paired end RNA-seq better than single-end for gene-wise gene expression analysis?

Image
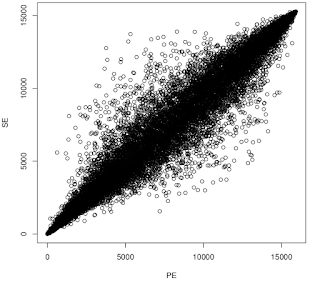
Something I've wondered about is whether for RNA-seq it's worth forking out the extra cost of sequencing both ends as opposed to single end. To test this, I went back to a paired end data set present in GEO ( GSE55123 , 2x 36bp), cleaned the data with Skewer, then mapped the reads with STAR in either paired-end mode or single-end mode (using just read 1). I then used featureCounts to quantify number of tags aligned to each gene. I excluded genes with fewer than 10 reads per sample on average. Then I ran edgeR at Degust  to identify differentially expressed genes (DEGs@FDR<0.05). I used a shell script to quantify the overlap in DEGs. Then I ranked them based on the p-value from most up-regulated to most down-regulated and compared their positions in the rank. Here's the result of the overlap analysis. You can see that PE fastq detected more genes but identified fewer DGEs than SE. Detected in PE:15919 Detected in SE: 15275 Detected in both:14750 Detected in eit...

Weighing the benefits of RNA-seq error correction

Image
Sequencing data contains two major types of errors, ones that are incorporated during library preparation and ones incorporated during sequence reading. While errors of the former are difficult to correct as they occur without clues from the base quality scores, the latter type do correlate with lower base quality scores and so it is possible to identify these ambiguous base calls and compare them to a library of high confidence k-mers from the same sequencing run. Error correction of this type has been show to improve de novo assemblies and SNP detection. A recent report posted in bioRxiv  shows error correction gives a drastic improvement in transcriptome assembly, with the author benchmarking the performance of five different correction software packages (Bless, Lighter, SGA, SEECER & BFC). The author reports that these software options vary in the aggressiveness of error correction, with SGA being the most aggressive, Lighter the least aggressive and BFC and SEECER per...

Generate an RNA-seq count matrix with featureCounts

Featurecounts is the fastest read summarization tool currently out there and has some great features which make it superior to HTSeq or Bedtools multicov. FeatureCounts takes GTF files as an annotation. This can be downloaded from the Ensembl FTP site . Make sure that the GTF version matches the genome that you aligned to. FeatureCounts it also smart enough to recognise and correctly process SAM and BAM alignment files. Here is a script to generate a gene-wise matrix from all BAM files in a directory. #!/bin/bash #Generate RNA-seq matrix #Set parameters GTF=/path/to/Mus_musculus.GRCm38.78.gtf EXPTNAME=mouse_rna CPUS=8 MAPQ=10 GENEMX=${EXPTNAME }_genes.mx #Make the gene-wise matrix featureCounts -Q $MAPQ -T $CPUS -a $GTF -o /dev/stdout *bam \ | cut -f1,7- | sed 1d > $GENEMX The data are now ready to analyse with your favourite statistical package (DESeq, EdgeR, Voom/Limma, etc). Consider attaching the gene name to give the data more relevance. To do that, first ...